Every AI reporting tool demo goes the same way. A sales engineer types a question in plain English, a clean chart appears in two seconds, and everyone in the room nods. Six months later your team is still exporting to spreadsheets, because the answers never quite matched the numbers finance already had.
That gap between demo and production is where budgets die. Gartner predicts that over 40% of agentic AI projects will be canceled by the end of 2027 because of escalating costs, unclear business value, or inadequate risk controls. Reporting deployments stall for exactly the same three reasons.
The useful part is that most of those failures are predictable. You can surface them during evaluation if you test the right things in the right order. Here is the framework.
Start With the Problem, Not the Product Category
Before you compare a single vendor, write down what is actually broken. "We need AI reporting" is not a requirement. These are:
- Business users wait five to twelve days for an ad hoc report.
- Three departments report different revenue numbers for the same quarter.
- The answers you need sit in PDFs and contracts that no dashboard can read.
- Analysts spend most of their week rebuilding the same repeat requests.
Each of those points to a different tool. A backlog problem points toward self-service analytics. A conflicting-numbers problem points toward a shared metric layer and governance. A documents problem rules out most business intelligence reporting tools immediately, because they only query structured tables.
Put your top three problems on one page and score every vendor against them. Anything that does not move those three is a feature, not a reason to buy.
Test Accuracy on Your Data, Not the Demo Dataset
This is the criterion buyers skip most often, and it decides whether anyone still trusts the tool in month three.
Public benchmarks give you a sense of the ceiling. On BIRD, a widely used benchmark for turning questions into SQL, Google Cloud reported a top single-model score of 76.13 against a human expert baseline of 92.96. BIRD spans more than 12,500 question and SQL pairs across 95 databases. Those are curated conditions. Your schema is messier than that.
Build a 50-question accuracy set before the demos start
Write 50 real questions your team asks, and record the correct answer for each one from your existing system. A useful mix looks like this:
- Ten simple lookups: Last month’s revenue by region.
- Fifteen cross-system questions: Anything that needs a join across two or more sources.
- Ten definition-dependent questions: Ones that hinge on internal terms like "active customer" or "net new ARR."
- Ten ambiguous questions: Deliberately underspecified, to see what the tool does with them.
- Five unanswerable questions: The data does not exist, and the tool should say so.
Then score each vendor. What matters is not raw accuracy but the failure mode. A tool that asks which revenue definition you mean is safer than one that confidently returns a wrong number. Ask every vendor to show you the generated text-to-SQL query behind each answer. If you cannot inspect the logic, you cannot audit the result.
Interrogate Security and Access Control Before the Pilot
AI reporting software sits on top of your most sensitive data, so run this as a security review rather than a software purchase.
IBM’s 2026 Cost of a Data Breach Report found that more than 20% of organizations reported a breach targeting AI models or applications, with compromised APIs, applications or plug-ins (27%) and cloud misconfigurations affecting AI workloads (27%) as the most common causes. The same study found that only 37% of breached organizations encrypt sensitive data both at rest and in transit.
Put these on the vendor questionnaire:
- Does the tool inherit row-level and column-level permissions from the source system, or maintain a separate copy?
- Where is your data processed, and is any of it used to train shared models?
- Are SSO, MFA, and role-based access control native, or an enterprise add-on?
- What does the audit log capture: the question, the generated query, the result set, or all three?
- How are connectors and API integrations secured and rotated?
Gartner also predicts that by 2028, 50% of organizations will implement a zero-trust posture for data governance as unverified AI-generated content spreads. Buying a reporting tool with no lineage or audit trail moves your data governance posture in the opposite direction.
Map Connectivity, Freshness, and Coverage
A logo wall of supported connectors tells you very little. Push on three things instead.
- Depth of connection: Does the tool read live from your warehouse, or replicate data on a schedule? A 24-hour refresh cycle disqualifies most operations use cases before you start.
- Unstructured coverage: A large share of enterprise answers live in policies, contracts, invoices and decks. Ask whether the tool can query documents alongside tables in a single question, or whether that needs a second product and a second budget line.
- Semantic consistency: If two teams phrase the same question differently, do they get the same number? Tools without a shared metric layer quietly reintroduce the conflicting-numbers problem you were trying to solve. This is the clearest dividing line between real conversational analytics and a chat wrapper on a database.
Model Total Cost, Not License Price
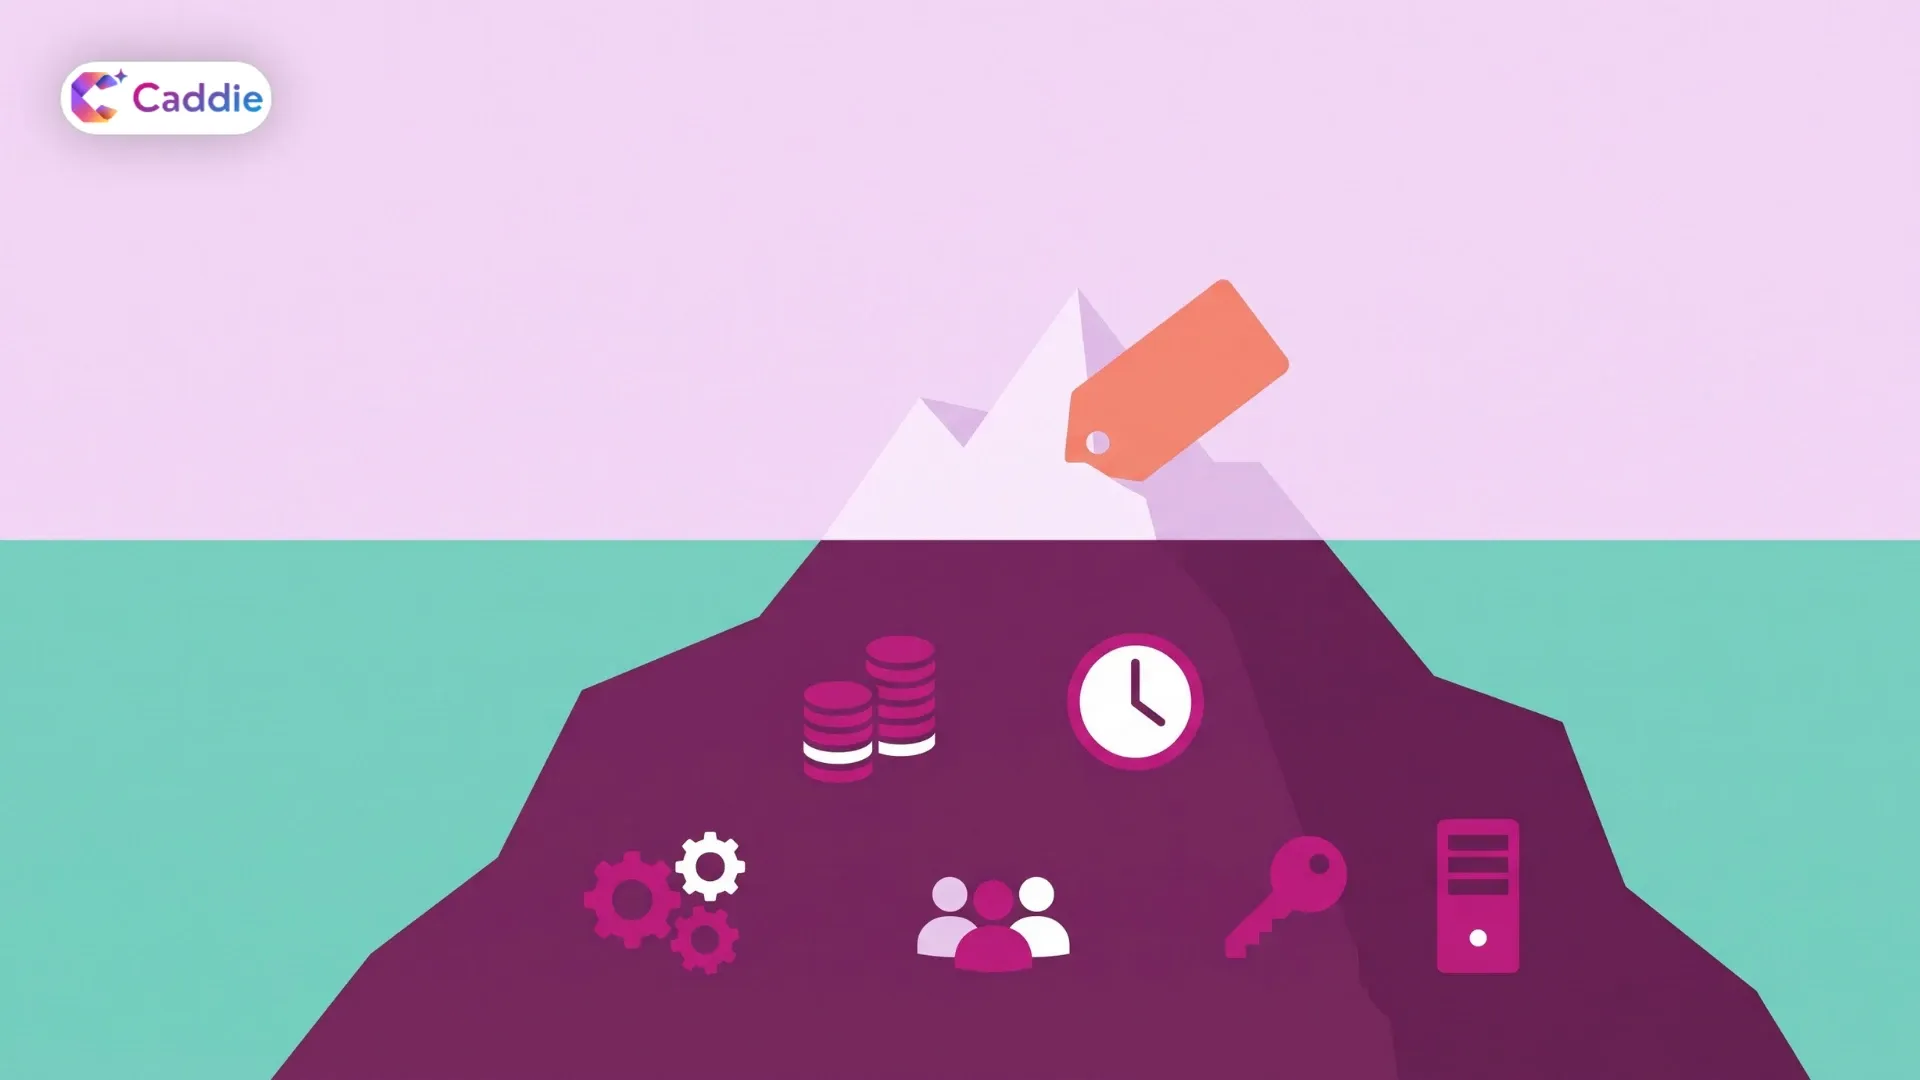
The sticker price of enterprise reporting software is usually the smallest line in the model. Build three years and include:
- Licenses, split by tier, since most vendors price viewers and creators differently
- Query or token consumption charges, which move sharply once adoption grows
- Implementation and data preparation, often the largest first-year cost
- Internal admin time for permissions, definitions and metric maintenance
- Training and change management for the business users who will actually ask the questions
- The legacy reporting stack you keep running in parallel during migration
Then ask the vendor a direct question: what happens to our bill if usage triples? Consumption pricing is fine, but you need the curve, not the starting point. Compare that total against what your current BI tools cost today, including the analyst hours spent on repeat requests.
Run a Proof of Concept With Exit Criteria Written First
Most pilots fail because nobody defined success before starting. Scope yours to four to six weeks, two data sources, and one business team with a real reporting pain. Then write the pass or fail thresholds in advance:
Accuracy: A target score on your 50-question set, with zero confident wrong answers on financial questions.
Adoption: At least 60% of the pilot group asking a question in week four without being prompted.
Time to answer: A median under 60 seconds for questions that used to take days.
Security: Permissions verified by your own team against at least three test user roles.
Support: Response times measured during the pilot, not promised in the contract.
Run it on your own messy data, not a cleaned sample the vendor prepared, and make sure your team drives the tool for the final two weeks rather than the vendor’s solutions engineer. Decide up front who owns AI governance for the deployment, because that owner will write the usage policy you need on day one.
Red Flags Worth Slowing Down For
The demo only uses vendor data. If they will not connect to a sandbox of yours during evaluation, assume integration is harder than advertised.
Accuracy is described without a number. "Highly accurate" is not a metric. Ask for measured accuracy on a named benchmark and on customer data.
The tool claims to act on its own. Gartner has flagged "agent washing," the rebranding of assistants, RPA and chatbots as agentic products, and estimates only about 130 of the thousands of agentic AI vendors are real. In reporting, autonomy is usually a liability. You want a tool that surfaces evidence so a human makes the call.
Governance is on the roadmap. Lineage, audit logs and permissions are not features you bolt on after rollout.
Every reference customer is smaller than you. Ask to speak with someone at your data volume, under your compliance regime, and at least a year into production.
Where Caddie Fits
Caddie is an enterprise AI assistant that lets business users ask questions of live data in plain language and get evidence-backed answers. It queries structured databases and unstructured documents in one place, returns charts and tables your team can share or export, and enforces SSO, MFA and role-based access so people only see what they should. Caddie helps your people reach decisions faster. It does not act on your behalf, which keeps a human accountable for every call and makes it far easier to pass the security and governance reviews above.
See how Caddie scores against your own evaluation criteria. Book a demo.
Frequently Asked Questions
What is an AI reporting tool?
An AI reporting tool lets users ask questions in natural language and returns charts, tables and written summaries from connected data sources, without manual query writing or dashboard building.
How long should an AI reporting tool evaluation take?
Plan eight to twelve weeks: two for requirements, two to three for demos and scoring, and four to six for a proof of concept on your own data.
Are AI reporting tools accurate enough for finance?
They can be, with guardrails. Require a shared metric layer, visible generated queries and audit logs, then validate against known figures before any financial use.
What should an AI reporting tool cost?
Pricing varies by seats, consumption and deployment model. Build a three-year total including implementation, admin time and query charges rather than comparing headline license rates.
Do AI reporting tools replace BI platforms?
Rarely at first. Most enterprises run both, using conversational tools for ad hoc questions and existing BI platforms for governed, recurring operational reports.